
Executive Summary & Key Takeaways
Key Insights- Separate ingress, routing, inference, autoscaling, and observability concerns.
- Use TTFT, tail latency, queue depth, GPU memory, and throughput—not CPU alone—to understand capacity.
- Benchmark vLLM, SGLang, or TensorRT-LLM with your real workload before production selection.
Quick Definition / Direct Answer
Direct SummaryProduction AI serving needs more than a load balancer: combine health-aware routing, workload-aware autoscaling, GPU/KV-cache monitoring, batching, admission control, and measurable latency SLOs. Benchmark the complete inference stack under realistic prompt, output, and concurrency distributions before choosing a serving runtime.
Short answer: A production cloud-native AI serving layer should separate model execution from request routing, scale on workload signals, and make latency, throughput, GPU utilization, and error budgets observable. Load balancing alone does not make an inference system reliable; routing, queueing, autoscaling, model warm-up, and failure handling have to work together.
What is cloud-native model serving?
Cloud-native model serving is the deployment of an inference model behind a network-accessible service that can scale horizontally, expose health signals, and recover from instance or node failures. For LLM workloads, the serving layer also has to manage GPU memory, KV cache pressure, batching, streaming, and sometimes multiple model replicas.
Why does load balancing matter for AI inference?
AI requests are not uniform. Prompt length, output length, concurrency, and model choice can change GPU time dramatically. A basic round-robin load balancer can therefore send two requests that have very different resource requirements to the same replica.
Need AI or Software Engineering Support?
Turn your ideas and technical challenges into reliable, scalable solutions with Acadify. From AI development and automation to software engineering and product development, we help businesses build and grow with confidence.
A stronger design combines request routing with queue depth, replica health, model availability, and workload-aware limits. The goal is not simply to distribute requests evenly; it is to keep each replica inside its latency and memory SLOs.
Reference architecture
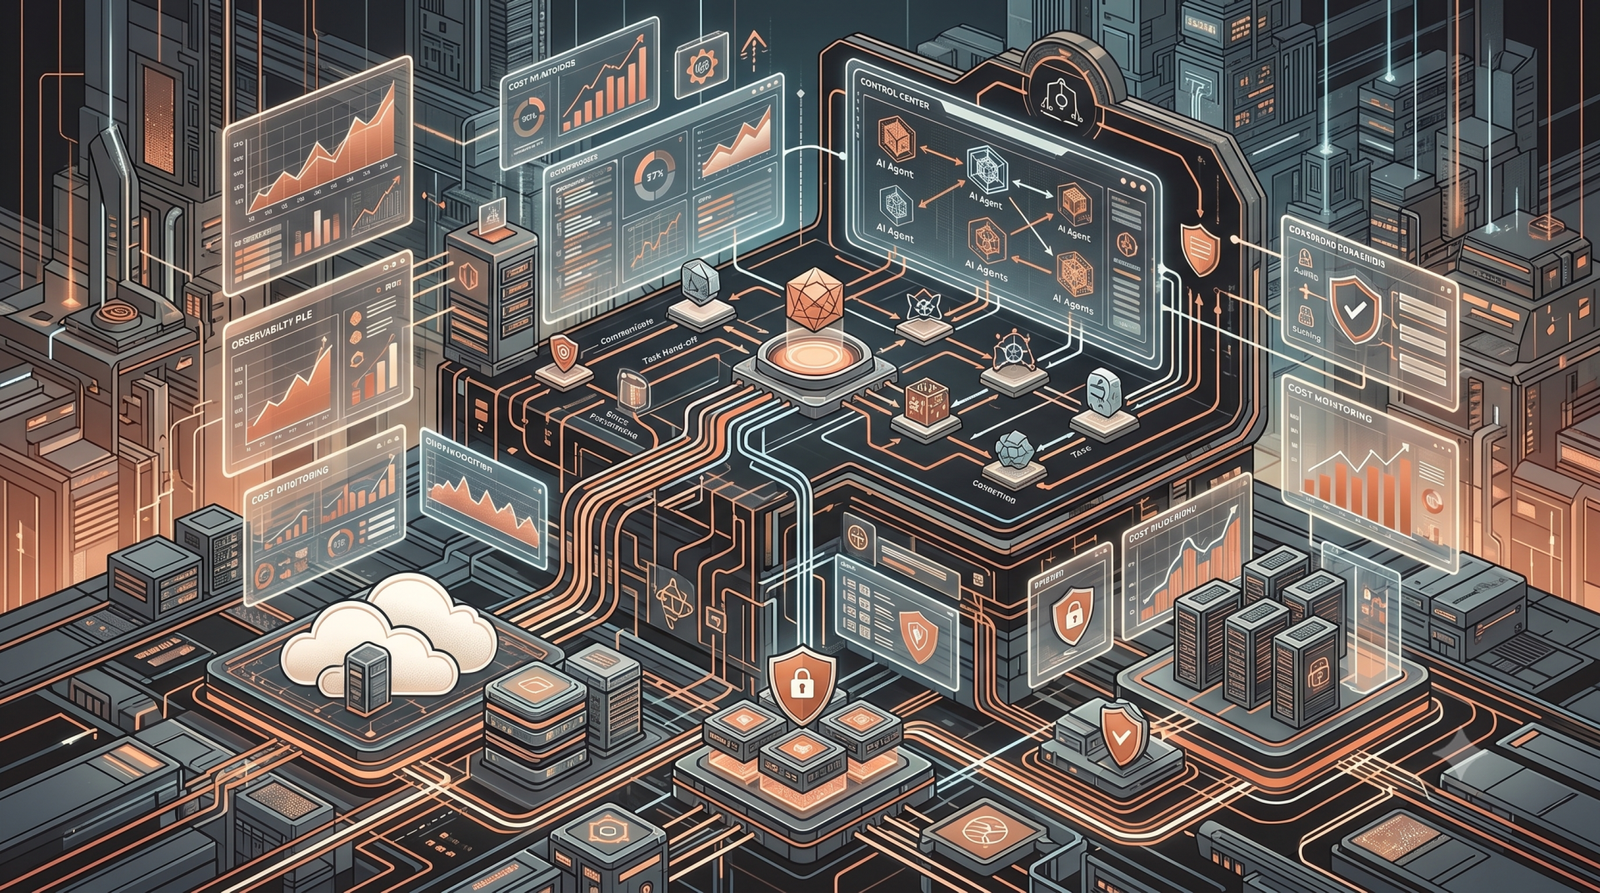
- Ingress/API gateway: authentication, rate limits, request validation, and tenant controls.
- Model router: selects the correct model or replica and applies routing policies.
- Inference replicas: vLLM, SGLang, TensorRT-LLM, or another production serving runtime.
- Autoscaler: scales using signals such as queue depth, concurrency, GPU utilization, TTFT, and tokens/sec rather than CPU alone.
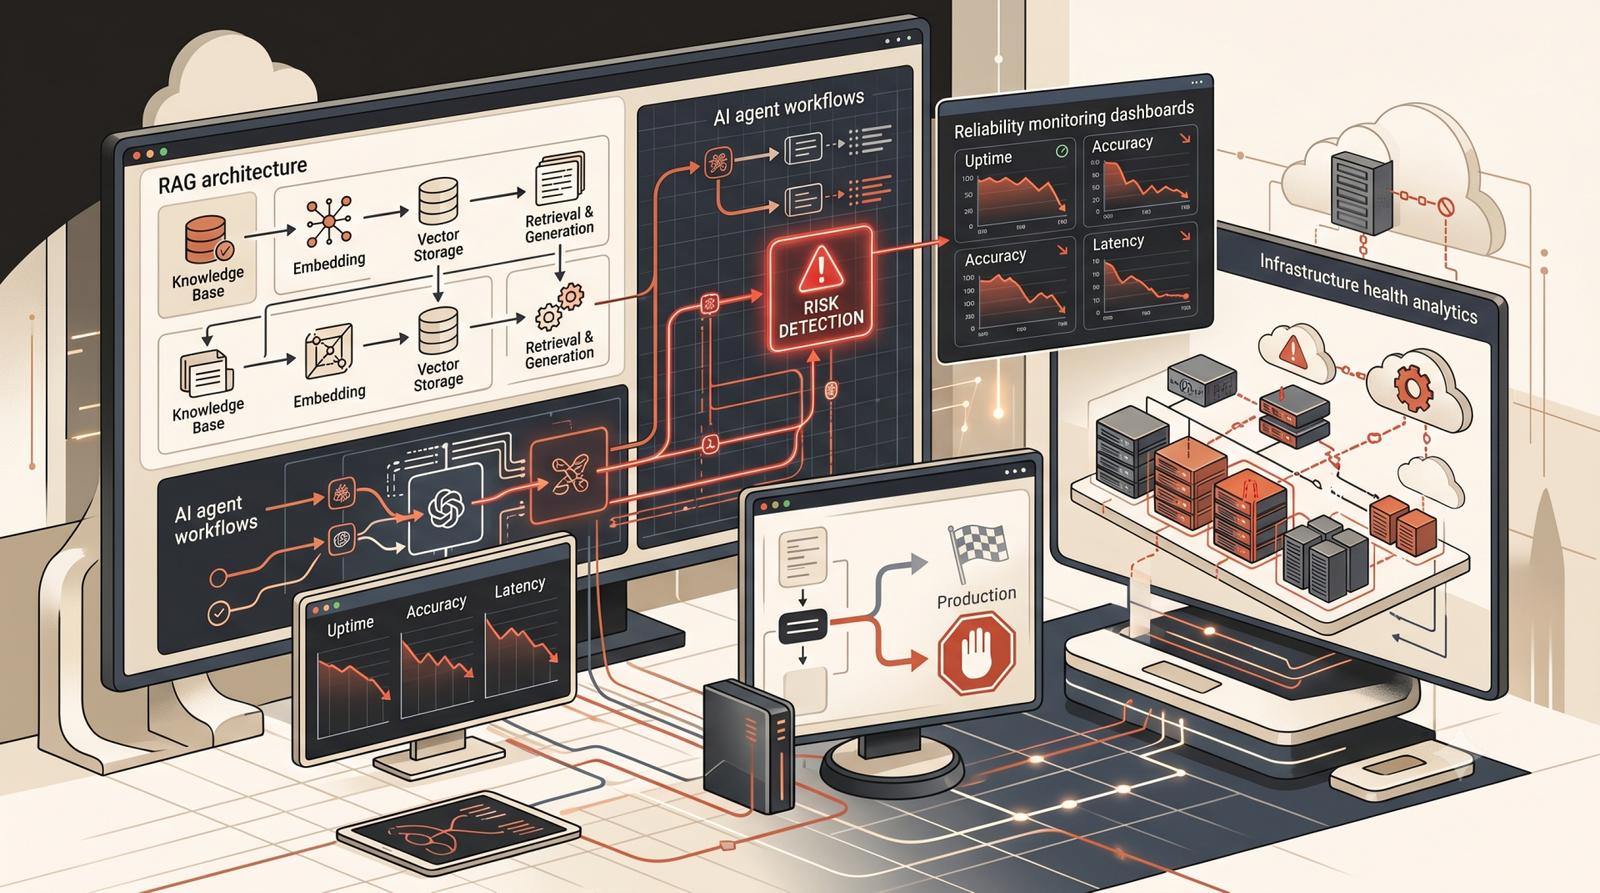
- Observability: captures TTFT, time per output token, end-to-end latency, throughput, errors, GPU memory, and saturation.
How should an AI load balancer route requests?
Start with health-aware routing and then add workload-aware policies. Useful signals include queue depth, active requests, estimated input/output tokens, model availability, and replica warm-up state.
For multi-tenant systems, keep tenant isolation and rate limits outside the model process. For multi-model fleets, avoid sending a request to a replica that would require an expensive model load unless the routing policy explicitly allows it.
Autoscaling: what should trigger a new replica?
CPU utilization is usually an incomplete signal for GPU inference. A practical autoscaling policy combines queue depth or waiting requests with GPU memory pressure, active sequences, throughput, and latency SLOs. Scale-in should be slower than scale-out so that short traffic spikes do not cause replica churn.
Reliability and failure handling
- Use readiness probes that verify the model is actually ready to serve, not merely that the process is alive.
- Drain a replica before termination so active generations can finish or fail predictably.
- Apply bounded retries only to requests that are safe to retry.
- Use circuit breakers or admission control when downstream capacity is exhausted.
- Keep model artifacts versioned and support rollback to a known-good deployment.
What should you measure?
| Signal | Why it matters |
|---|---|
| TTFT | Measures responsiveness before the first generated token. |
| Time per output token | Shows generation efficiency after decoding begins. |
| P95/P99 latency | Exposes tail behavior hidden by averages. |
| Queue depth | Shows demand exceeding immediately available capacity. |
| GPU memory/KV cache pressure | Helps prevent overload and admission failures. |
| Tokens/sec | Useful for capacity planning and cost modeling. |
How do modern serving runtimes help?
vLLM provides PagedAttention, continuous batching, prefix caching, quantization, distributed parallelism, and an OpenAI-compatible API. TensorRT-LLM provides in-flight batching, paged attention, multi-GPU/multi-node inference, and NVIDIA GPU optimizations. SGLang provides RadixAttention, continuous batching, prefix caching, structured outputs, and distributed serving features. These capabilities change the bottleneck profile, so benchmark the complete workload rather than assuming a runtime is faster in every scenario.
Production checklist
- Define TTFT, generation-latency, throughput, and availability SLOs.
- Load-test with realistic prompt and output-length distributions.
- Measure P50, P95, and P99 instead of average latency alone.
- Test replica startup, draining, GPU exhaustion, and dependency failures.
- Track cost per million input/output tokens or another workload-normalized unit.
- Keep routing and autoscaling policies version-controlled.
Key takeaway
High-performance enterprise AI serving is a systems problem. The winning architecture is the one that keeps inference capacity predictable under real workload distributions while making latency, cost, reliability, and failure behavior measurable.
Glossary & Key Architecture Definitions
- • Model serving: exposing a trained model through a production inference service.
- • TTFT: time to first token, measuring responsiveness before generation begins.
- • SLO: service-level objective defining an operational target such as latency or availability.
- • KV cache: attention state retained during autoregressive generation.
Engineering Research & Citations
- [1] vLLM documentation: https://docs.vllm.ai/en/stable/
- [2] TensorRT-LLM documentation: https://nvidia.github.io/TensorRT-LLM/
- [3] SGLang documentation: https://www.sglang.io/
No perspectives submitted yet. Be the first to start the discussion.