
Executive Summary & Key Takeaways
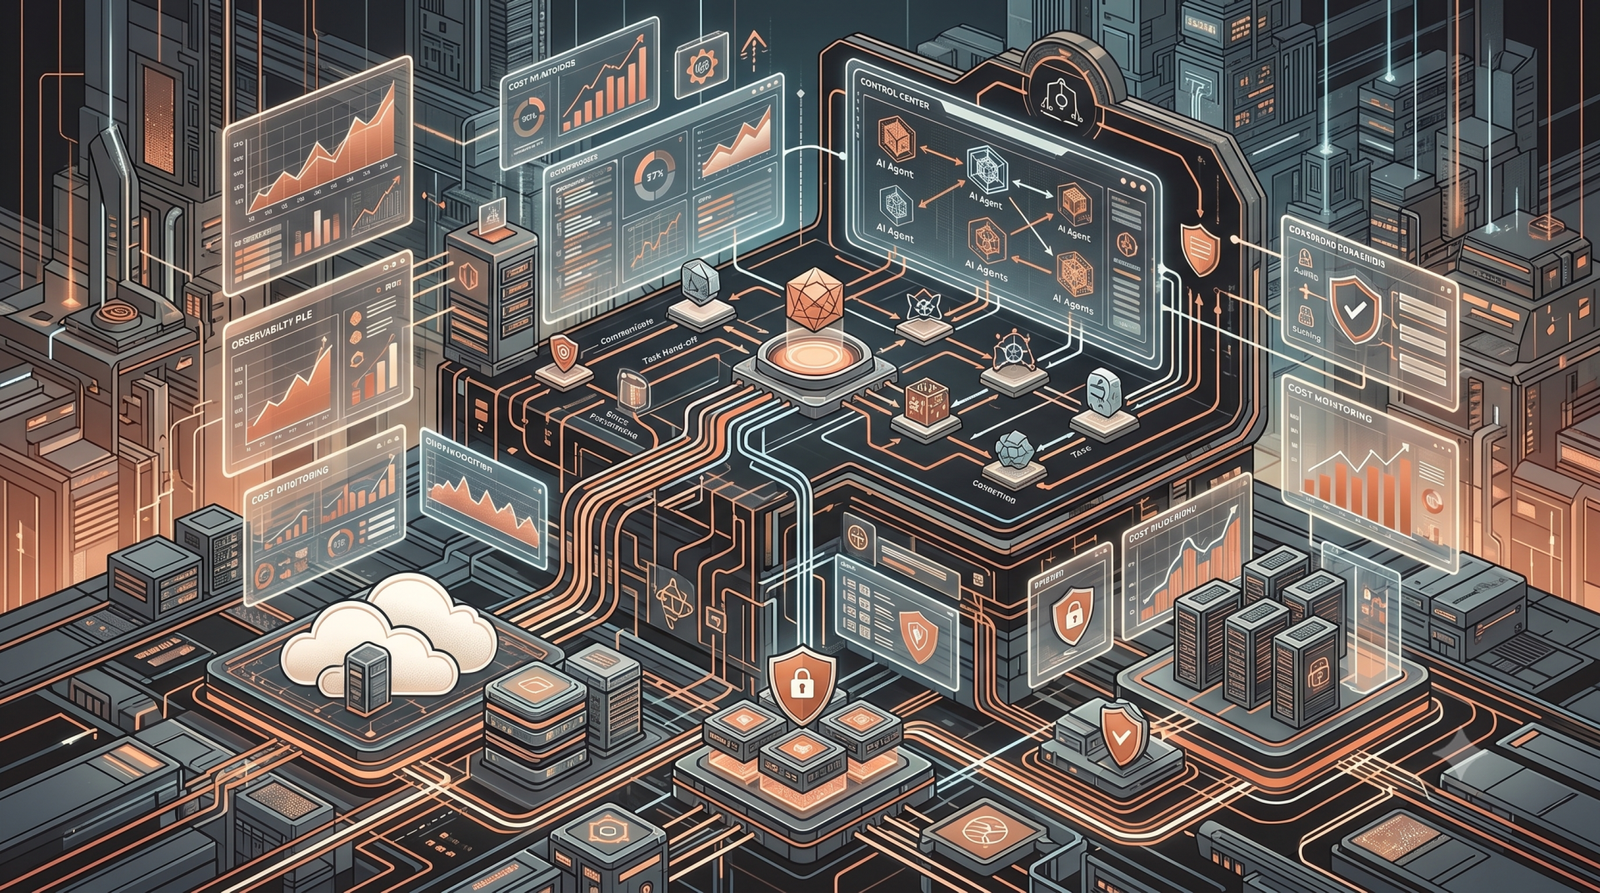
Key Insights- Separate ingress, routing, inference, autoscaling, and observability layers.
- Scale using workload-aware signals such as queue depth, concurrency, latency, and GPU pressure.
- Use readiness checks, bounded retries, graceful draining, and rollback paths.
- Benchmark with realistic prompt, output, and concurrency distributions.
Quick Definition / Direct Answer
Direct SummaryCloud-native enterprise AI model serving is a production architecture for exposing models through scalable inference endpoints with health-aware load balancing, autoscaling, observability, and controlled model rollout. The design should optimize latency, throughput, availability, and cost against explicit workload SLOs.
Optimizing Cloud-Native Enterprise AI with Real-Time Model Serving
What Is Cloud-Native Enterprise AI Model Serving?
Cloud-native enterprise AI model serving exposes models through scalable inference endpoints with health-aware routing, autoscaling, observability, and controlled model rollout. Production systems should optimize latency, throughput, availability, and cost against explicit workload SLOs.
Real-Time Model Serving with TensorFlow Serving
import tensorflow as tf
from tensorflow_serving.api import model_server

# Load the model
model = tf.keras.models.load_model("model.h5")

# Create a TensorFlow Serving model server
server = model_server.ModelServer(model)

# Start the server
server.start()
TensorFlow Serving is a popular framework for real-time model serving. It provides a simple and efficient way to serve machine learning models in real-time. With TensorFlow Serving, you can handle high-volume requests and achieve low-latency applications.
Load Balancing for Distributed Systems
How Should AI Model Serving Use Load Balancing?
AI model serving should route requests across healthy workers using model affinity, capacity, queue depth, and readiness signals. Measure p50, p95, and p99 latency, throughput, GPU utilization, errors, and queue time so routing and autoscaling decisions reflect actual workload pressure.
Need AI or Software Engineering Support?
Turn your ideas and technical challenges into reliable, scalable solutions with Acadify. From AI development and automation to software engineering and product development, we help businesses build and grow with confidence.
Load Balancing for Distributed Systems
Use a load balancer to distribute requests across healthy model-serving workers while respecting capacity and model affinity. Autoscaling should react to request rate, queue depth, GPU utilization, or another measurable saturation signal. Health checks should distinguish process liveness from model readiness.
Track p50, p95, and p99 latency, queue time, inference time, throughput, error rate, and GPU utilization. Apply bounded timeouts and controlled fallbacks when a worker or model endpoint becomes unavailable. During upgrades, drain active requests before replacing workers and compare the new version with a fixed regression workload.
Use a load balancer to distribute requests across healthy model-serving workers while respecting model affinity and capacity. Autoscaling should react to request rate, queue depth, GPU utilization, or another measurable saturation signal. Health checks should distinguish process liveness from model readiness.
Track p50, p95, and p99 latency, queue time, inference time, throughput, error rate, and GPU utilization. Apply bounded timeouts and controlled fallbacks when a worker or model endpoint becomes unavailable.
Load Balancing with HAProxy
frontend http
  bind *:80

  default_backend servers

backend servers
  mode http
  balance roundrobin
  server server1 192.168.1.100:8080 check
  server server2 192.168.1.101:8080 check
HAProxy is a popular load balancing solution for distributed systems. It provides a simple and efficient way to distribute incoming network traffic across multiple servers. With HAProxy, you can improve responsiveness and reliability in your distributed system.
Asynchronous Model Updates
Finally, asynchronous model updates are an essential technique for optimizing cloud-native enterprise AI. Asynchronous model updates involve updating machine learning models in the background while serving requests in real-time. This approach ensures seamless model serving and deployment, even when updating models.
Asynchronous Model Updates with TensorFlow
import tensorflow as tf

# Load the model
model = tf.keras.models.load_model("model.h5")

# Create a TensorFlow model
tf_model = tf.keras.models.Model(inputs=model.inputs, outputs=model.outputs)

# Update the model asynchronously
tf_model.update("new_model.h5")
TensorFlow provides a simple and efficient way to update machine learning models asynchronously. With TensorFlow, you can update models in the background while serving requests in real-time, ensuring seamless model serving and deployment.
Conclusion
Production Checklist for Model Serving
A production model-serving platform should be treated as a distributed system rather than a model endpoint. Start by defining the workload contract: expected request rate, concurrency, latency SLOs, payload limits, timeout budgets, availability targets, and acceptable fallback behavior. Then separate the gateway, routing, inference workers, model registry, autoscaling signals, and observability pipeline so each layer can be tested independently.
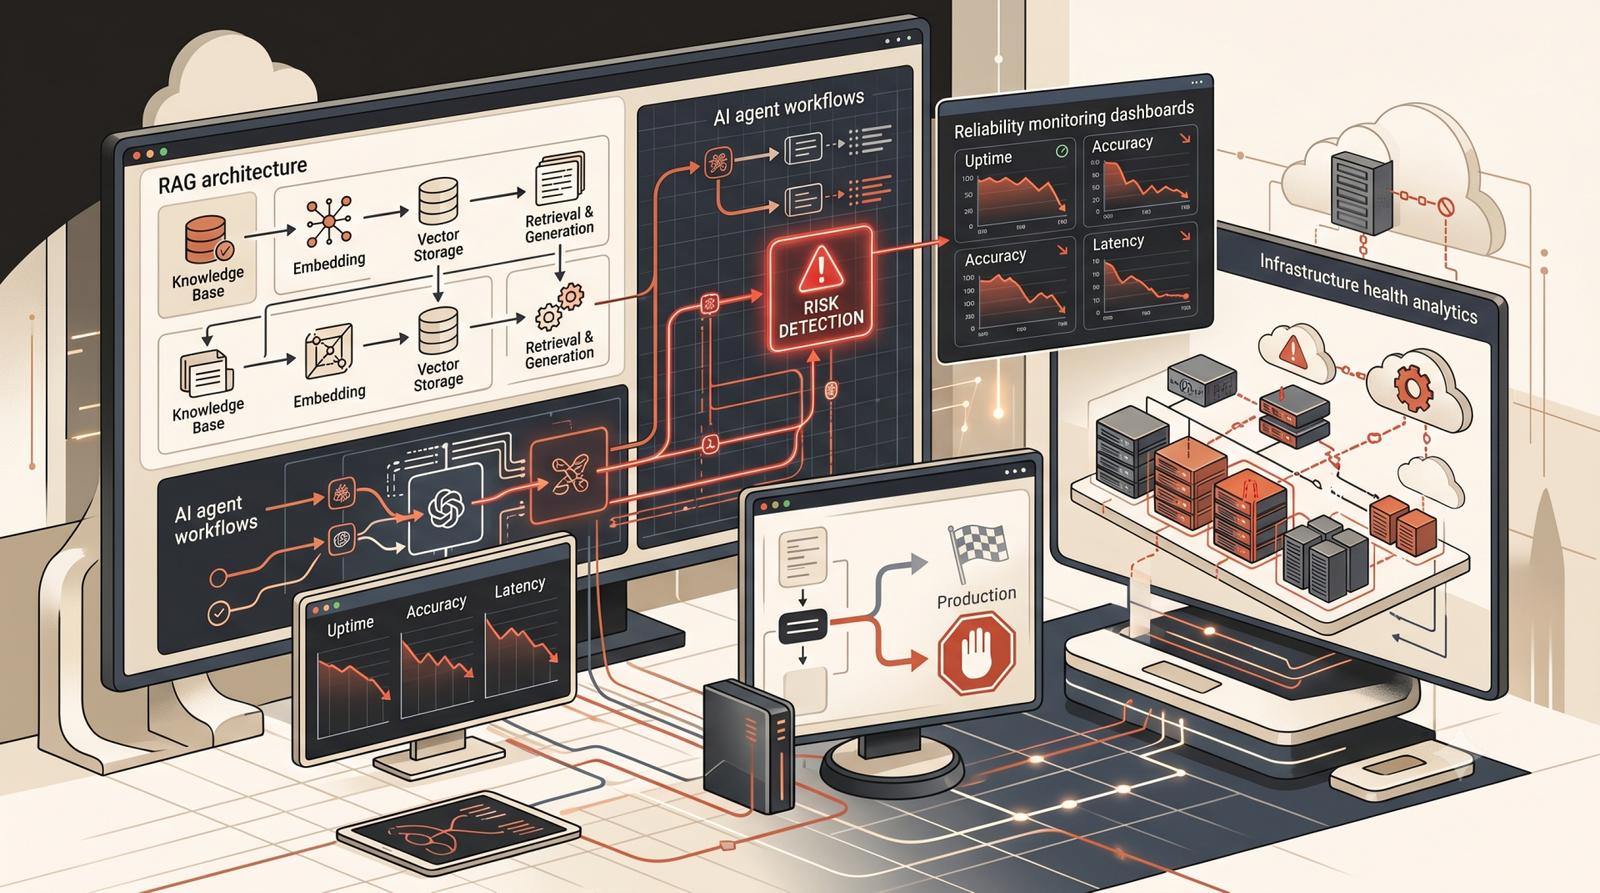
Before a release, run a representative workload rather than a single happy-path request. Measure p50, p95, and p99 latency, queue time, tokens or inference work per request, error rate, worker saturation, and recovery behavior when a worker becomes unhealthy. Test cold starts, rolling deployments, model loading failures, traffic spikes, and partial dependency failures. These tests reveal bottlenecks that functional validation alone will miss.
For high-availability deployments, combine readiness-aware routing with graceful connection draining and bounded retries. Keep retry budgets small so an overloaded inference tier does not amplify traffic. Canary new model versions against a fixed regression workload and retain a fast rollback path when quality, latency, or cost moves outside the agreed SLO envelope.
The result is a serving architecture that can scale with demand without turning every increase in traffic into a reliability or cost incident.
Glossary & Key Architecture Definitions
- • Cloud-native: An architecture designed to use elastic infrastructure, automation, and distributed operational primitives.
- • Model serving: Exposing a trained model through a production inference service.
- • SLO: A measurable reliability target such as latency or availability.
Engineering Research & Citations
- [1] Kubernetes documentation: https://kubernetes.io/docs/
- [2] KServe documentation: https://kserve.github.io/website/
- [3] vLLM documentation: https://docs.vllm.ai/en/stable/
- [4] RFC 9110 HTTP Semantics: https://www.rfc-editor.org/rfc/rfc9110
No perspectives submitted yet. Be the first to start the discussion.