
Executive Summary & Key Takeaways
Key Insights- Separate semantic caching from retrieval so each layer has a clear responsibility.
- Use tenant-aware cache keys, TTLs, and invalidation rules.
- Combine lexical and vector retrieval when both exact terms and semantic meaning matter.
- Monitor correctness, freshness, latency, and cost—not cache hit rate alone.
Quick Definition / Direct Answer
Direct SummaryA production semantic cache can reduce repeated retrieval and generation work, while hybrid search combines lexical and vector retrieval for stronger coverage. The design must enforce tenant isolation, freshness, invalidation, model-version boundaries, and observability so cached answers remain safe and useful.
A semantic cache can reduce repeated retrieval and model-work costs when similar user requests recur, while hybrid search combines lexical matching with semantic retrieval. In a production enterprise AI system, the two layers should be designed separately: the cache decides whether a previous result is reusable; the search layer retrieves fresh evidence when it is not.
What Is a Semantic Cache?
A semantic cache stores the result of an expensive operation against a representation of the request's meaning rather than relying only on an exact string match. This can help when users phrase equivalent questions differently. The cache should only return a result when its similarity threshold, freshness policy, tenant boundary, and data-validity rules are satisfied.
How Should Redis Fit Into the Architecture?
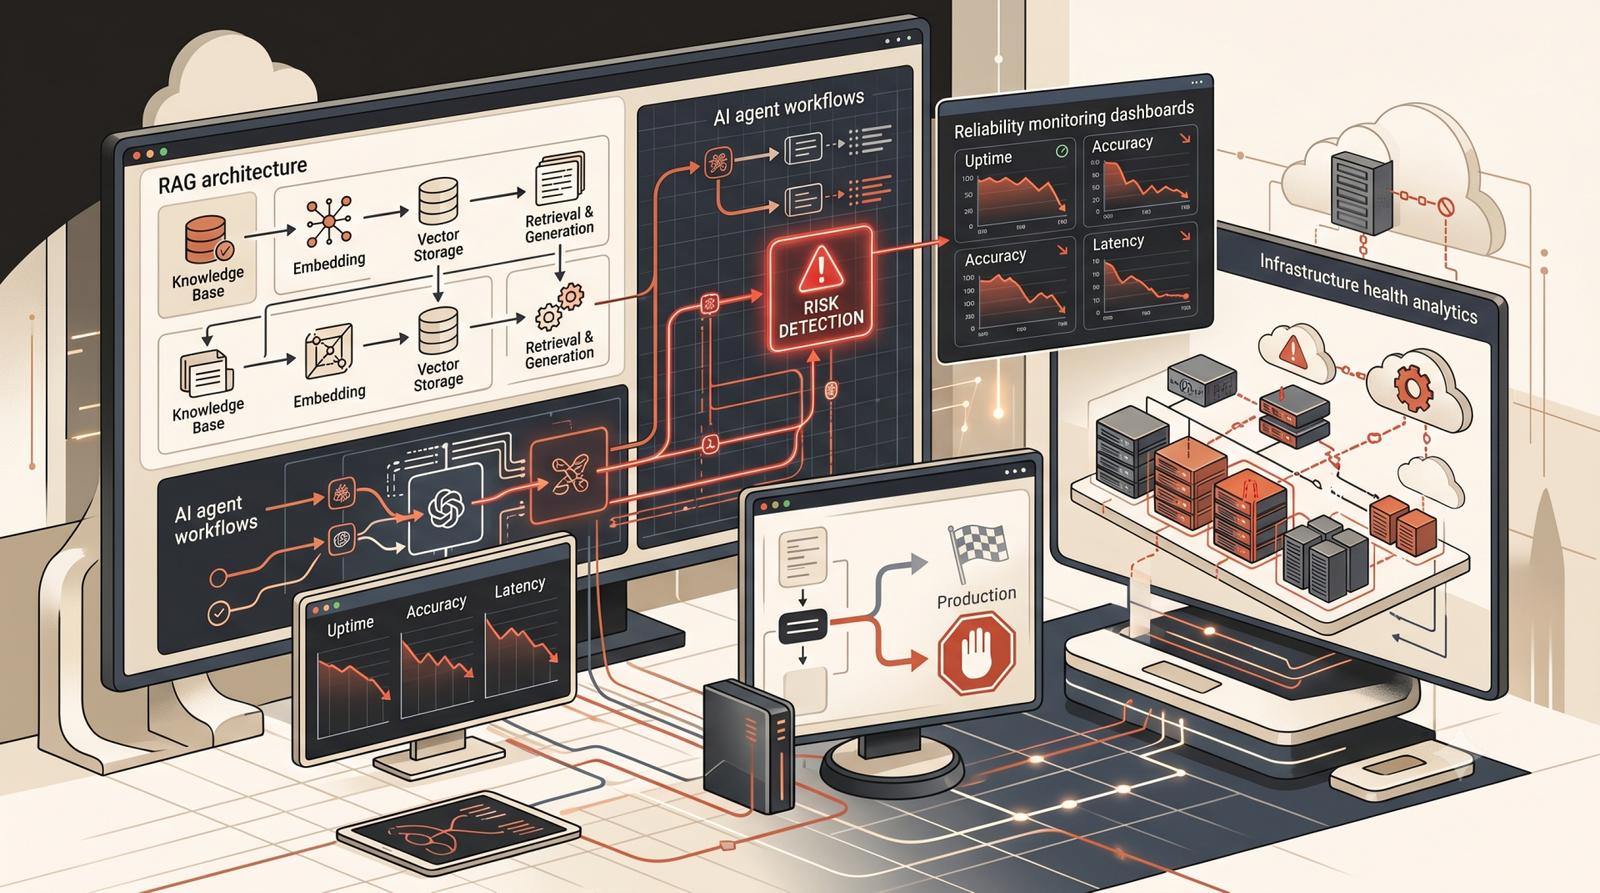
Redis can serve as a low-latency cache layer in front of retrieval and generation. A practical request path is: normalize the request, check authorization and tenant scope, calculate or retrieve an embedding, search the semantic cache, validate freshness, and either return the cached result or continue to hybrid retrieval and generation.
Need AI or Software Engineering Support?
Turn your ideas and technical challenges into reliable, scalable solutions with Acadify. From AI development and automation to software engineering and product development, we help businesses build and grow with confidence.
- Cache key: include tenant, model/version, retrieval configuration, and other dimensions that affect correctness.
- TTL: use a bounded lifetime for information that can become stale.
- Invalidation: invalidate affected entries when source documents or policies change.
- Observability: measure hit rate, false-hit rate, latency, and downstream cost rather than treating hit rate alone as success.
What Is Hybrid Search?
Hybrid search combines lexical retrieval, such as BM25, with vector similarity. Lexical search is useful for exact names, identifiers, product terminology, and rare words; vector retrieval is useful for semantic similarity. A production system can combine their ranked results with a documented fusion method and then rerank the strongest candidates when additional precision is required.
Production Request Flow
- Authenticate the request and establish tenant/data-access boundaries.
- Normalize the query and derive the cache identity.
- Check the semantic cache and validate freshness.
- If there is no safe cache hit, run lexical and vector retrieval.
- Fuse or rerank the candidate set.
- Generate the answer from the retrieved evidence.
- Cache only results that are safe to reuse under the application's policy.
What Can Go Wrong?
The biggest production risk is not cache latency; it is returning an answer that is no longer valid for the user or their data. Common failure modes include stale documents, cross-tenant cache leakage, embedding/model changes, permission changes, and caching answers whose correctness depends on rapidly changing state.
How Should You Monitor It?
- Cache hit and miss rates
- Cache lookup latency
- End-to-end retrieval latency
- Search result quality and reranker performance
- Stale-result or invalidation incidents
- Per-request model and retrieval cost
Frequently Asked Questions
Does semantic caching replace hybrid search?
No. A cache can avoid repeated work for reusable requests; hybrid search remains the retrieval mechanism when fresh evidence is required.
Should every AI response be cached?
No. Cache only responses whose freshness, authorization, personalization, and data-dependency requirements make reuse safe.
What should be invalidated first?
Invalidate entries affected by changed source data, permissions, model versions, retrieval configuration, or other correctness-critical dependencies.
Key Takeaways
- Separate cache correctness from retrieval quality.
- Use tenant-aware keys and explicit freshness rules.
- Combine lexical and semantic retrieval when both exact terms and meaning matter.
- Measure quality and correctness alongside latency and cache hit rate.
Technical references: Redis Search documentation and Elastic hybrid search documentation.
Production Cache Invalidation and Evaluation
Semantic caching needs explicit invalidation rules because a high-similarity response is not necessarily still correct. Tie cache entries to tenant identity, source-data freshness, model version, prompt version, and an application-defined time-to-live. Invalidate entries when underlying documents or business policies change.
Evaluate cache performance with hit rate, false-hit rate, freshness violations, p95 latency, retrieval savings, model calls avoided, and cost per request. Test semantically similar queries as well as intentionally different queries to ensure the similarity threshold does not return an incorrect answer.
Glossary & Key Architecture Definitions
- • Semantic cache: A cache that reuses results based on similarity of meaning rather than exact query text.
- • Hybrid search: Retrieval that combines lexical and vector search signals.
- • Cache invalidation: Removing or bypassing cached results when their underlying data or correctness assumptions change.
Engineering Research & Citations
- [1] Redis Search documentation: https://redis.io/docs/latest/develop/interact/search-and-query/
- [2] Elastic hybrid search documentation: https://www.elastic.co/docs/solutions/search/hybrid-search
No perspectives submitted yet. Be the first to start the discussion.