
Executive Summary & Key Takeaways
Key Insights- Preserve headings, tables, metadata, and source boundaries during chunking.
- Combine lexical and vector retrieval for complementary recall.
- Use reranking when evaluation shows a meaningful relevance improvement.
- Measure retrieval quality, groundedness, latency, cost, freshness, and authorization.
Quick Definition / Direct Answer
Direct SummaryProduction RAG combines document-aware chunking, hybrid retrieval, reranking, context assembly, and grounded generation. Preserve document structure and metadata during chunking, use lexical plus vector retrieval when both exact terms and semantic similarity matter, and add reranking when measured relevance gains justify the latency and cost.
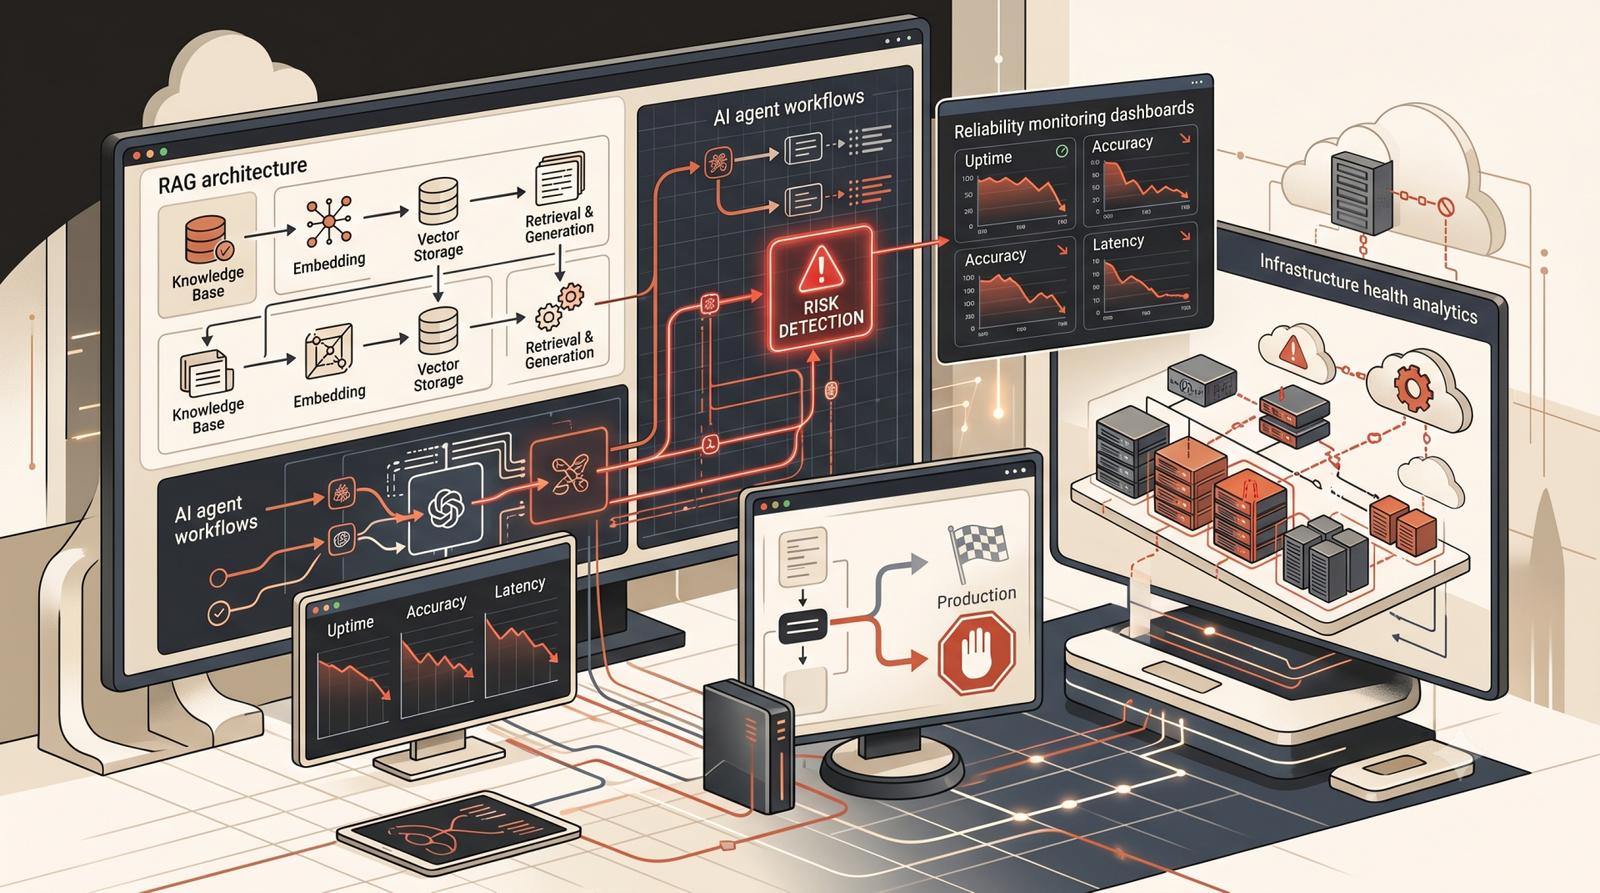
Production RAG quality depends on the complete retrieval pipeline: document parsing, chunking, indexing, retrieval, reranking, context assembly, generation, and evaluation. Hybrid chunking and reranking can improve retrieval quality, but neither guarantees a fixed latency or accuracy improvement across every workload.
What Problem Does Production RAG Solve?
Retrieval-augmented generation gives a language model access to external evidence at query time. The engineering goal is not simply to retrieve more documents; it is to retrieve the right evidence with enough context and low enough latency for the application's requirements.
How Should Hybrid Chunking Work?
Use different chunking strategies for different document structures. Headings, paragraphs, tables, lists, code, and metadata often carry different semantic boundaries. Preserve document identifiers and source locations so retrieved passages can be traced back to the original material.
Need AI or Software Engineering Support?
Turn your ideas and technical challenges into reliable, scalable solutions with Acadify. From AI development and automation to software engineering and product development, we help businesses build and grow with confidence.
- Keep chunks coherent enough to stand alone.
- Preserve parent-document and section metadata.
- Avoid splitting tables or code arbitrarily.
- Measure retrieval quality at realistic query lengths.
Why Add a Reranker?
Initial retrieval is optimized for recall and efficiency. A reranker can then examine a smaller candidate set and reorder results for relevance to the user's query. This two-stage design lets the system retrieve broadly and spend more computation on the candidates most likely to matter.
What Does a Production RAG Pipeline Look Like?
- Ingest and normalize source documents.
- Create structure-aware chunks with stable source metadata.
- Build lexical and vector indexes where appropriate.
- Retrieve a candidate set using one or more retrieval signals.
- Rerank candidates using a relevance model or deterministic policy.
- Assemble a bounded context for generation.
- Generate with citations or source references when the application requires them.
- Evaluate retrieval and answer quality continuously.
How Should Security and Privacy Be Designed?
Enforce document-level authorization before retrieved content reaches the model. Encrypt data in transit and at rest where appropriate, isolate tenants, minimize sensitive data in prompts and logs, and define retention policies. Retrieval must never bypass the source system's access controls.
How Do You Evaluate RAG?
- Retrieval: recall@k, precision@k, ranking quality, and source coverage.
- Answer quality: groundedness, completeness, relevance, and citation correctness.
- Operations: p50/p95/p99 latency, throughput, failure rate, and infrastructure cost.
Frequently Asked Questions
Does reranking always improve RAG?
No. It can improve ranking quality when the initial candidate set contains useful but poorly ordered results, but it adds latency and compute cost. Measure the trade-off on representative queries.
Is smaller chunk size always better?
No. Very small chunks can lose context, while very large chunks can reduce retrieval precision and waste context capacity. Chunk size should follow document structure and evaluation results.
Should every RAG system use vector search?
No. The appropriate retrieval design depends on the corpus and query patterns. Lexical search can be essential for identifiers and exact terminology, while vector search can help with semantic similarity.
Key Takeaways
- Optimize the entire retrieval pipeline rather than one component in isolation.
- Use structure-aware chunking and preserve source metadata.
- Use reranking when measured relevance gains justify its compute cost.
- Evaluate retrieval, groundedness, latency, cost, and security continuously.
Production Evaluation and Failure Handling
Hybrid chunking and reranking should be validated with a versioned evaluation set containing short questions, multi-hop queries, tables, long documents, ambiguous terms, and permission-sensitive requests. Measure candidate recall, reranker precision, grounded-answer rate, citation validity, p95 latency, error rate, and cost per successful answer.
Failure handling should be explicit. If retrieval returns insufficient evidence, the application should abstain or request clarification rather than fabricate an answer. If the reranker or vector store times out, use bounded retries and a controlled fallback. Preserve source identifiers so every generated answer can be traced back to retrieved evidence.
Production RAG quality depends on the entire retrieval pipeline, not only chunking. Preserve document structure, headings, tables, source identifiers, and access-control metadata when creating chunks. Hybrid retrieval can combine lexical matching for exact identifiers with vector retrieval for semantic similarity, while reranking improves ordering of the candidate set.
Evaluation should separate retrieval quality from generation quality. Measure candidate recall, reranker precision, grounded-answer rate, citation validity, p95 latency, error rate, cache hit rate, and cost per successful answer. Use a versioned regression dataset containing normal queries, long documents, ambiguous questions, tables, multi-hop requests, and permission-sensitive cases.
Failure handling should be deterministic. If retrieval returns insufficient evidence, the application should abstain or ask for clarification rather than fabricate an answer. If a vector store or reranker times out, use bounded retries and a controlled fallback. Preserve source identifiers so every generated answer can be traced to retrieved evidence.
Glossary & Key Architecture Definitions
- • RAG: Retrieval-augmented generation that supplies retrieved external evidence to a language model at query time.
- • Chunking: Splitting source content into retrievable units while preserving enough context for accurate retrieval.
- • Reranking: Reordering retrieved candidates with a more precise relevance model or scoring policy.
Engineering Research & Citations
- [1] Retrieval-Augmented Generation survey: https://arxiv.org/abs/2312.10997
- [2] Elasticsearch hybrid search: https://www.elastic.co/docs/solutions/search/hybrid-search
- [3] OpenAI retrieval guide: https://platform.openai.com/docs/guides/retrieval
No perspectives submitted yet. Be the first to start the discussion.