Executive Summary & Key Takeaways
• Enhance enterprise AI performance
• Boost AI trust and adoption
1. Overview
Building an AI system that users trust is a daunting task, even with the advent of cloud-based services and open-source frameworks. Enterprise AI teams often spend months optimizing prompts, experimenting with different models, and integrating Retrieval-Augmented Generation (RAG) systems. However, one question remains unanswered: how do you know your AI is actually getting better? Benchmark scores provide only a partial picture, while manual spot checks do not scale. User feedback is inconsistent and usually arrives after mistakes reach production. This is where ASR-based AI evaluation becomes valuable.
Benchmark Analysis
| Benchmark Type | Limitations |
|---|---|
| Automated Benchmarks | Do not reflect real production behavior, proprietary data, evolving workflows, and instructions |
| Manual Spot Checks | Do not scale, inconsistent, and usually arrive after mistakes reach production |
| User Feedback | Inconsistent, subjective, and usually arrives after mistakes reach production |
What Is ASR-Based AI Evaluation?
ASR stands for Assessment, Scoring, and Recommendation. It is a structured evaluation methodology where human evaluators assess AI-generated responses against predefined quality dimensions and provide recommendations that engineering teams can act on. Unlike simple thumbs-up or thumbs-down feedback, ASR captures why a response succeeds or fails. This transforms subjective opinions into measurable quality data.
The ASR Evaluation Workflow
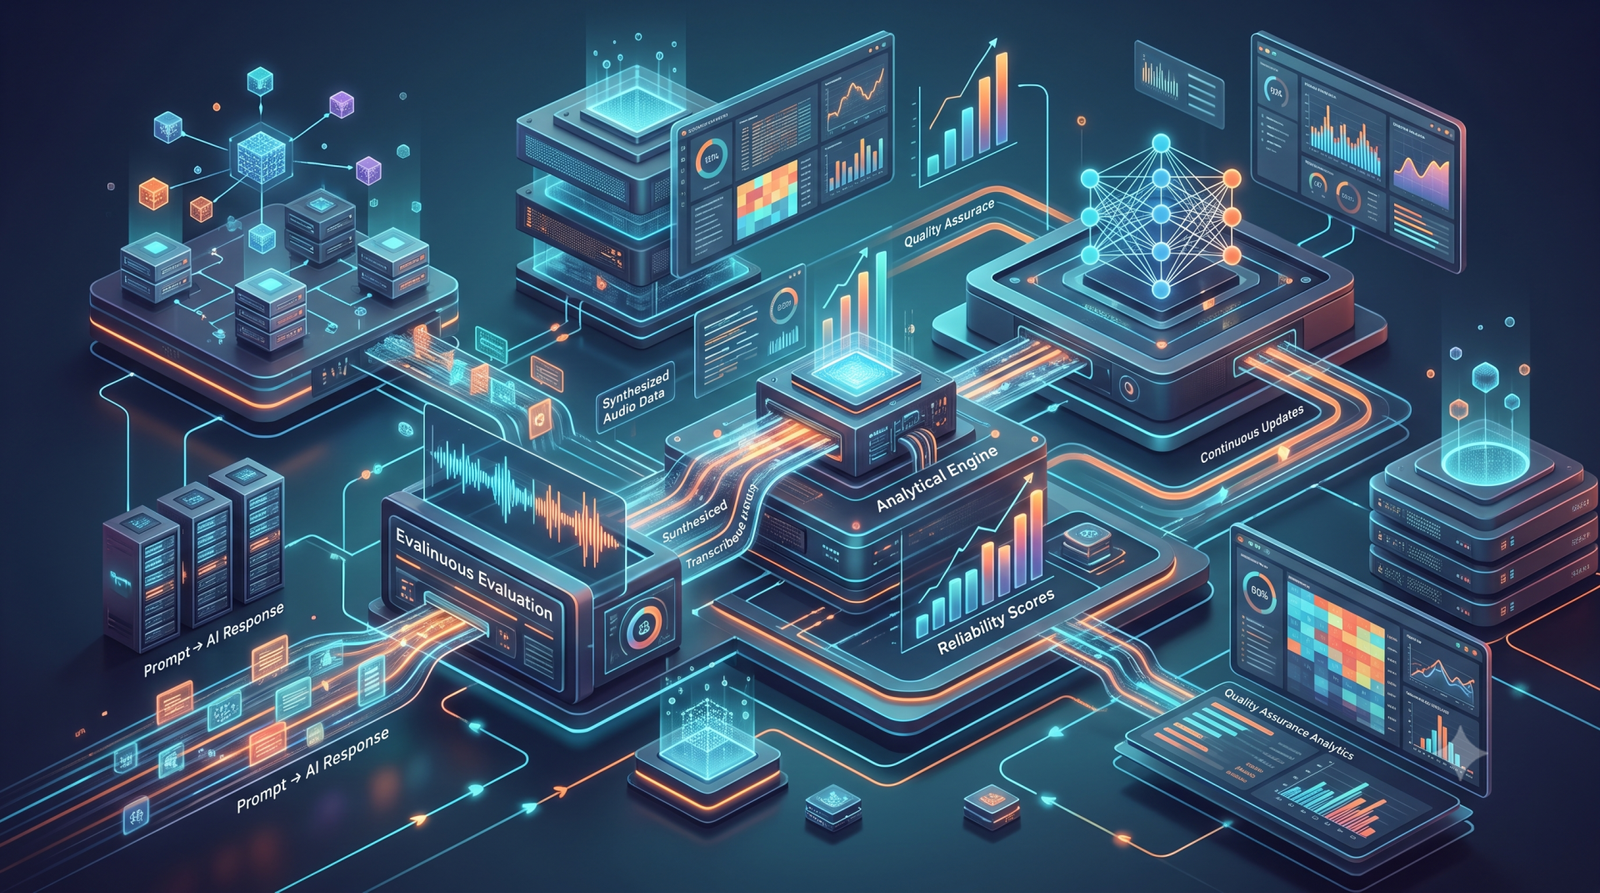
A production-ready ASR workflow typically follows these stages:
Need MVP Development or AI Solutions?
Turn your idea into reality with Acadify. Fast, scalable, and built for enterprise growth.
- Prompt submission
- AI response generation
- Human evaluation
- Structured scoring
- Failure categorization
- Engineering recommendations
- Continuous improvement
Each evaluation contributes to a growing dataset that helps engineering teams identify recurring weaknesses across prompts, workflows, and models.
Implementation Snippet
# Production implementation
import os
import json

# Define the ASR evaluation workflow
def asr_evaluation(prompt, response, evaluation_dimensions):
    # Human evaluation
    human_evaluation = evaluate_response(prompt, response)

    # Structured scoring
    scores = score_response(response, evaluation_dimensions)

    # Failure categorization
    failures = categorize_failures(scores)

    # Engineering recommendations
    recommendations = generate_recommendations(failures)

    return human_evaluation, scores, failures, recommendations

# Example usage
prompt =
No perspectives submitted yet. Be the first to start the discussion.